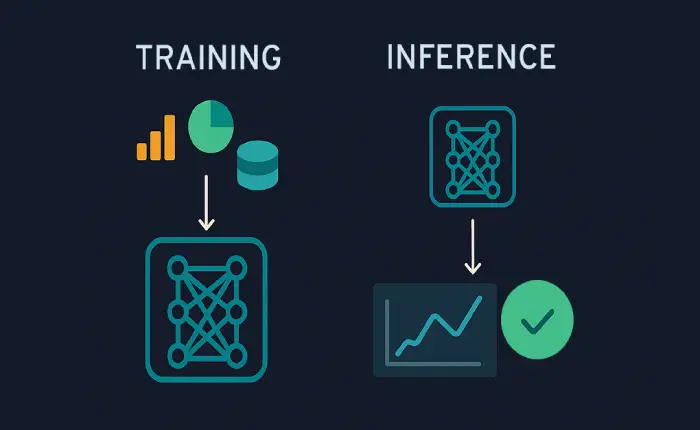
AI inference engineering focuses on running trained artificial intelligence models efficiently, reliably, and at scale. This course explores the systems, architectures, and optimization techniques used to serve machine learning and large language models, from inference APIs and resource management to production deployment.
Learners explore batch and online inference, latency, throughput, memory management, request scheduling, caching, and model serving architectures. The curriculum also covers LLM token generation, context windows, KV caching, continuous batching, quantization, pruning, knowledge distillation, GPU optimization, multi-GPU systems, and distributed inference.
Production engineering receives dedicated attention through scalability, autoscaling, monitoring, reliability, API security, and cost management. Through structured projects, learners build inference APIs, optimize models, deploy LLM services, benchmark performance, implement monitoring, and design production-ready inference systems.